GLM 5.3 API Key Setup: Same Price as 5.2, 10x Cheaper Flash
Set up a GLM 5.3 API key on OurToken. Same per-token price as GLM 5.2, plus a Flash variant at one-tenth the cost. cURL and Python examples.
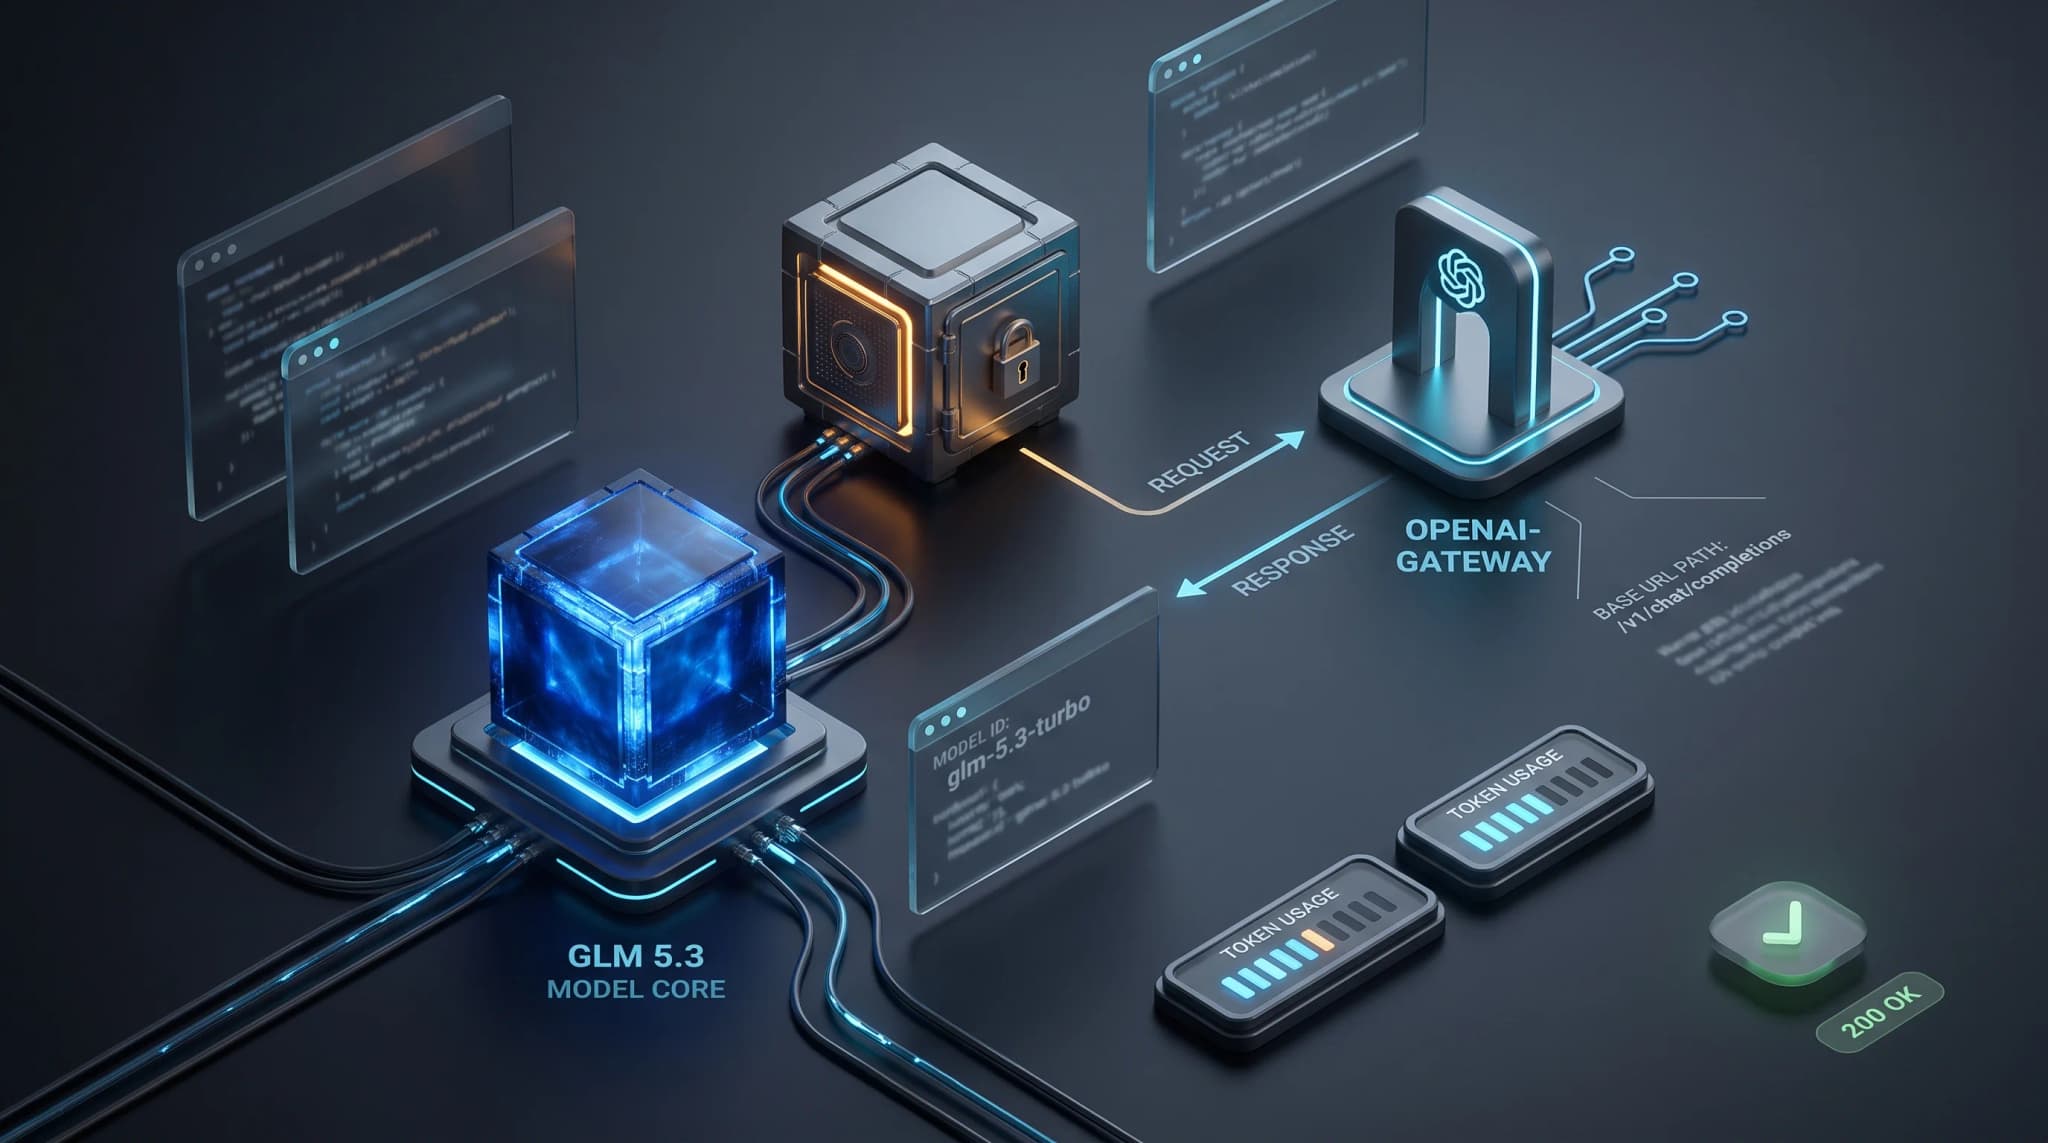
A GLM 5.3 API key is only useful when the credential, endpoint, model ID, and request body all point at the same route. GLM 5.3 is the flagship route of the GLM 5 family on OurToken: a frontier model aimed at reasoning, coding agents, and long-context production workloads. It is worth setting up for one reason above the others — it upgrades the GLM 5.2 route at the same per-token price, while its Flash sibling gets near-frontier coding at one-tenth the cost.
This guide walks through a GLM 5.3 API setup through OurToken: where to create the key, the exact endpoint and model ID, a cURL smoke test, a Python example using the OpenAI SDK, usage accounting, and how GLM 5.3, GLM 5.3 Flash, and the GLM 5.2 route fit together. The route used here is:
https://api.ourtoken.ai/v1/chat/completions
Verification status: This article is documentation-verified against the public OurToken GLM 5.3 page, the OurToken GLM 5.3 Flash page, and the official Z.ai models reference, all checked on 2026-10-13. Prices and model IDs can change; confirm the live model page before committing to a budget.
GLM 5.3 API Setup at a Glance
For the primary example, use the GLM 5.3 route on OurToken. Keep these values in configuration rather than scattering them across application code.
| Setting | OurToken value | Why it matters |
|---|---|---|
| API key | OURTOKEN_API_KEY | Authenticates the request |
| SDK base URL | https://api.ourtoken.ai/v1 | The URL passed to an OpenAI-compatible client |
| Full API endpoint | https://api.ourtoken.ai/v1/chat/completions | The URL used by cURL or a raw HTTP client |
| Model ID | glm-5.3 | Selects the GLM 5.3 route |
| Required body fields | model, messages | Identifies the model and conversation |
| Context window | 1M input / 128K output | Matches the route's long-context spec |
The distinction between the SDK base URL and the full endpoint is easy to miss. An OpenAI-compatible Python client appends /chat/completions for the chat method, so its base_url should end at /v1. A raw cURL request does not append anything; it should use the complete /v1/chat/completions URL. |
The GLM 5.3 route family
OurToken exposes three GLM 5 routes that suit different workloads:
| Route | Model ID | Typical starting point |
|---|---|---|
| GLM 5.3 | glm-5.3 | Frontier reasoning, coding agents, long-context production workloads |
| GLM 5.3 Flash | glm-5.3-flash | Cost-efficient coding and agent workloads; 18B active parameters, near-frontier coding |
| GLM 5.2 | glm-5.2 | The prior-generation route, kept for existing integrations |
These are model IDs, not website slugs. Do not copy a catalog path such as glm/glm-5.3 into the JSON model field. For this article, every request uses the exact OurToken value glm-5.3.
All three routes use the OpenAI-compatible Chat Completions shape through OurToken, so a client that already talks to GPT, DeepSeek, or Qwen routes on OurToken can switch to GLM without changing transport.
Get and Test a GLM 5.3 API Key
An API key authenticates programmatic access. For the OurToken route, open the OurToken API Keys page, create or select a key, and keep it server-side. Use an environment variable during local development:
On macOS or Linux:
export OURTOKEN_API_KEY="paste-your-key-locally"
On Windows PowerShell:
$env:OURTOKEN_API_KEY = "paste-your-key-locally"
The HTTP request sends the secret in the standard header:
Authorization: Bearer YOUR_API_KEY
Do not put the key in frontend JavaScript, a mobile app bundle, a public Git repository, or a blog post. Logs should record a request ID, status code, model ID, latency, and redacted usage data rather than the authorization header.
cURL smoke test
The following is a minimal non-streaming request through OurToken, using the full endpoint:
curl -sS https://api.ourtoken.ai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer ${OURTOKEN_API_KEY}" \
  -d '{
    "model": "glm-5.3",
    "messages": [
      {
        "role": "user",
        "content": "Give me a three-step checklist for reviewing a database migration."
      }
    ],
    "max_tokens": 256
  }'
Once this succeeds, add one change at a time: temperature, stream, tools, or a structured response format. If a new field causes a 400 response, remove that field and compare it with the current OurToken model reference instead of assuming every field from the official GLM API is supported by every compatibility layer.
What a successful response should contain.
For a non-streaming Chat Completions response, inspect the structural fields:
{
  "id": "chatcmpl-redacted",
  "object": "chat.completion",
  "model": "glm-5.3",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "1. Review the schema changes.\n2. Test rollback.\n3. Validate production impact."
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 30,
    "completion_tokens": 24,
    "total_tokens": 54
  }
}
This is an illustrative response shape, not a live response captured from an OurToken account. When cache details are returned, prompt_tokens_details.cached_tokens is a breakdown of the input total; do not add cached tokens on top of the full prompt count when estimating cost.
Common cURL mistakes.
| Symptom | Likely cause | Fix |
|---|---|---|
401 Unauthorized | Missing, expired, or wrong-provider key | Check OURTOKEN_API_KEY and use the OurToken key with the OurToken URL |
404 Not Found | Wrong path or model value | Use /v1/chat/completions and glm-5.3 |
400 for an invalid body | Malformed JSON or missing messages | Validate the JSON and send an array of role/content messages |
400 after adding an option | The route does not accept that optional field | Remove it, then verify support on the live model page |
429 Too Many Requests | Rate limit or account capacity | Slow down, use bounded backoff, and avoid unlimited retries |
Do not retry a 400, 401, or 404 unchanged. Those responses indicate a configuration or request problem, not a transient provider failure.
GLM 5.3 Python API Usage
The official OpenAI Python library can be configured with a compatible base URL:
python -m pip install --upgrade openai
Then create a client with the OurToken base URL. The base URL ends at /v1; the SDK adds the Chat Completions operation when you call client.chat.completions.create.
import os

from openai import OpenAI


client = OpenAI(
    api_key=os.environ["OURTOKEN_API_KEY"],
    base_url="https://api.ourtoken.ai/v1",
)

response = client.chat.completions.create(
    model="glm-5.3",
    messages=[
        {
            "role": "system",
            "content": "You are a concise software engineering assistant.",
        },
        {
            "role": "user",
            "content": "List the checks for a safe database migration.",
        },
    ],
    max_tokens=256,
)

print(response.choices[0].message.content)

if response.usage:
    usage = response.usage
    cached_details = getattr(usage, "prompt_tokens_details", None)
    print(
        {
            "prompt_tokens": usage.prompt_tokens,
            "completion_tokens": usage.completion_tokens,
            "total_tokens": usage.total_tokens,
            "cached_tokens": getattr(cached_details, "cached_tokens", 0),
        }
    )
Keep the first Python request deterministic. For a smoke test, keep the input short and the output cap low. The following checks are more useful than simply printing a successful string:
assert response.model == "glm-5.3"
assert response.choices
assert response.choices[0].message.role == "assistant"
assert response.choices[0].message.content is not None
In an application, replace assertions with structured error handling and telemetry. The test should fail loudly if a gateway returns a different model or an empty message.
GLM 5.3 vs GLM 5.2: What Changed
If you already call GLM 5.2 on OurToken (the GLM 5.2 API key setup guide covers that route), the move to GLM 5.3 is a model ID change with no price change — a free capability upgrade in token terms.
| Dimension | GLM 5.3 | GLM 5.2 |
|---|---|---|
| Positioning | Frontier reasoning, coding agents, long-context production workloads | Multilingual chat, reasoning, production workflows |
| Context window | 1M input / 128K output | 1M tokens |
| Flash sibling | GLM 5.3 Flash, 18B active parameters, near-frontier coding | None listed |
| Input price | $0.84 / 1M | $0.84 / 1M |
| Output price | $2.64 / 1M | $2.64 / 1M |
Because the per-token price is identical, upgrading an existing GLM 5.2 integration to glm-5.3 costs nothing in token terms. The real decision is GLM 5.3 versus its Flash sibling.
GLM 5.3 vs GLM 5.3 Flash
GLM 5.3 Flash is the cost-optimized variant on OurToken: 18B active parameters with a 1M context window. It keeps the same long-context capability as the flagship at roughly one-tenth of the input and output price.
| Route | Input | Output | Cached input | Cache writes |
|---|---|---|---|---|
GLM 5.3 (glm-5.3) | $0.8400 / 1M | $2.6400 / 1M | $0.1560 / 1M | $0 / 1M |
GLM 5.3 Flash (glm-5.3-flash) | $0.0900 / 1M | $0.3000 / 1M | $0.0180 / 1M | $0 / 1M |
If your workload is high-volume or latency-sensitive, Flash is the cheaper default; reserve GLM 5.3 itself for tasks where the flagship's deeper reasoning actually pays off. If your application needs to route between them, the LLM model routing guide is the playbook for sending simple requests to a cheap route and complex requests to a strong one instead of standardizing on a single model.
GLM 5.3 API Pricing on OurToken
OurToken lists its GLM 5 routes at 60% of the official reference price. The current per-million-token rates are:
| Route | Input | Output | Cached input | Cache writes |
|---|---|---|---|---|
GLM 5.3 (glm-5.3) | $0.8400 / 1M | $2.6400 / 1M | $0.1560 / 1M | $0 / 1M |
GLM 5.3 Flash (glm-5.3-flash) | $0.0900 / 1M | $0.3000 / 1M | $0.0180 / 1M | $0 / 1M |
For 100,000 input tokens and 20,000 output tokens on GLM 5.3:
Input:  100,000 / 1,000,000 * $0.8400 = $0.08400
Output:  20,000 / 1,000,000 * $2.6400 = $0.05280
Total:                                  = $0.13680
For a repeated-context request with 80,000 cached input tokens and 20,000 uncached input tokens on GLM 5.3, the input side is:
Cached input:   80,000 / 1,000,000 * $0.1560 = $0.01248
Uncached input: 20,000 / 1,000,000 * $0.8400 = $0.01680
Input total:                                  = $0.02928
The second calculation assumes the route reports cached tokens in prompt_tokens_details and bills them at the cached-input rate. Cached tokens are a subset of input tokens, so never count the full prompt price and the cached price for the same tokens. See the LLM API pricing guide for the general accounting pattern.
Prices change. Use the live OurToken model page as the source of truth for billing, and re-check it when you set a quarterly budget.
From a Smoke Test to a Production Integration
A first response proves only that one request passed. A production integration also needs secret management, a model allowlist, and a clear fallback.
Request architecture. Keep the API key on a server or trusted worker. A browser should call your application backend, not expose the OurToken credential directly:
User or internal service
          |
          | application request
          v
Your backend / job worker
          |
          | Authorization: Bearer OURTOKEN_API_KEY
          v
https://api.ourtoken.ai/v1/chat/completions
          |
          | model = glm-5.3
          v
GLM 5.3 route
          |
          v
Assistant response + usage data
          |
          v
Redacted logs, budget checks, and application output
Model allowlist. The backend should own the model mapping. Do not accept an arbitrary model string from an untrusted client and pass it directly to the gateway:
MODEL_IDS = {
    "quality": "glm-5.3",
    "economy": "glm-5.3-flash",
}


def resolve_model(name: str) -> str:
    try:
        return MODEL_IDS[name]
    except KeyError as exc:
        raise ValueError("Unsupported model selection") from exc
Release checklist. Before using a GLM 5.3 API key with real users:
- The key is available only to a server process or protected worker.
- cURL succeeds against
https://api.ourtoken.ai/v1/chat/completions. - The request uses
glm-5.3, not a website slug or display label. - The Python SDK uses
base_url="https://api.ourtoken.ai/v1". - The response model and choice role are validated.
- Usage records use
prompt_tokens,completion_tokens, andtotal_tokens. - Cached tokens are not counted twice in cost calculations.
- 400, 401, 404, 429, timeout, and 5xx behavior is tested.
- Optional tools, streaming, or structured output are enabled one at a time and verified on the live model route.
Conclusion
The reliable GLM 5.3 API setup is compact: create an OurToken key, set https://api.ourtoken.ai/v1 as the SDK base URL, call /chat/completions, and send the exact glm-5.3 model ID. Start with the short cURL request, repeat it in Python, inspect the response usage, and only then add tools, streaming, or larger prompts.
When you are ready to test the integration with a real credential, review the GLM 5.3 API configuration and create a key through the OurToken API Keys page. If your workload is high-volume or latency-sensitive rather than frontier-quality-driven, evaluate GLM 5.3 Flash on the same endpoint before defaulting to the flagship.
FAQ
What is the GLM 5.3 API endpoint on OurToken?
The full endpoint is https://api.ourtoken.ai/v1/chat/completions. For the OpenAI Python SDK, set base_url to https://api.ourtoken.ai/v1 and call client.chat.completions.create.
What is the GLM 5.3 model ID?
Use glm-5.3 on OurToken. Do not send glm/glm-5.3 as the API model value.
What is the GLM 5.3 price on OurToken?
As of 2026-10-13, $0.8400 / 1M input, $2.6400 / 1M output, $0.1560 / 1M cached input, and $0 cache writes, listed at 60% of the official reference. Confirm the live model page before budgeting.
Can I use the OpenAI Python SDK for GLM 5.3?
Yes. Install the openai package, set the OurToken base URL, read the key from OURTOKEN_API_KEY, and call the Chat Completions method with model="glm-5.3".
Should I use GLM 5.3 or GLM 5.3 Flash?
Use GLM 5.3 when frontier reasoning or coding-agent quality is the priority. Use GLM 5.3 Flash for high-volume or latency-sensitive workloads; it keeps the 1M context at roughly a tenth of the input price.
What is the difference between GLM 5.3 and GLM 5.2?
On OurToken the per-token price is the same, but GLM 5.3 is the newer flagship with a Flash sibling at 18B active parameters. Choose GLM 5.3 for new integrations; keep GLM 5.2 only if an existing integration depends on it.