Claude Sonnet 5 Pricing: Official Rates vs a 40% Route
Claude Sonnet 5 pricing explained: $2/$10 official rates, cache and thinking costs, worked monthly scenarios, and how to run the same model at 40% of official price.
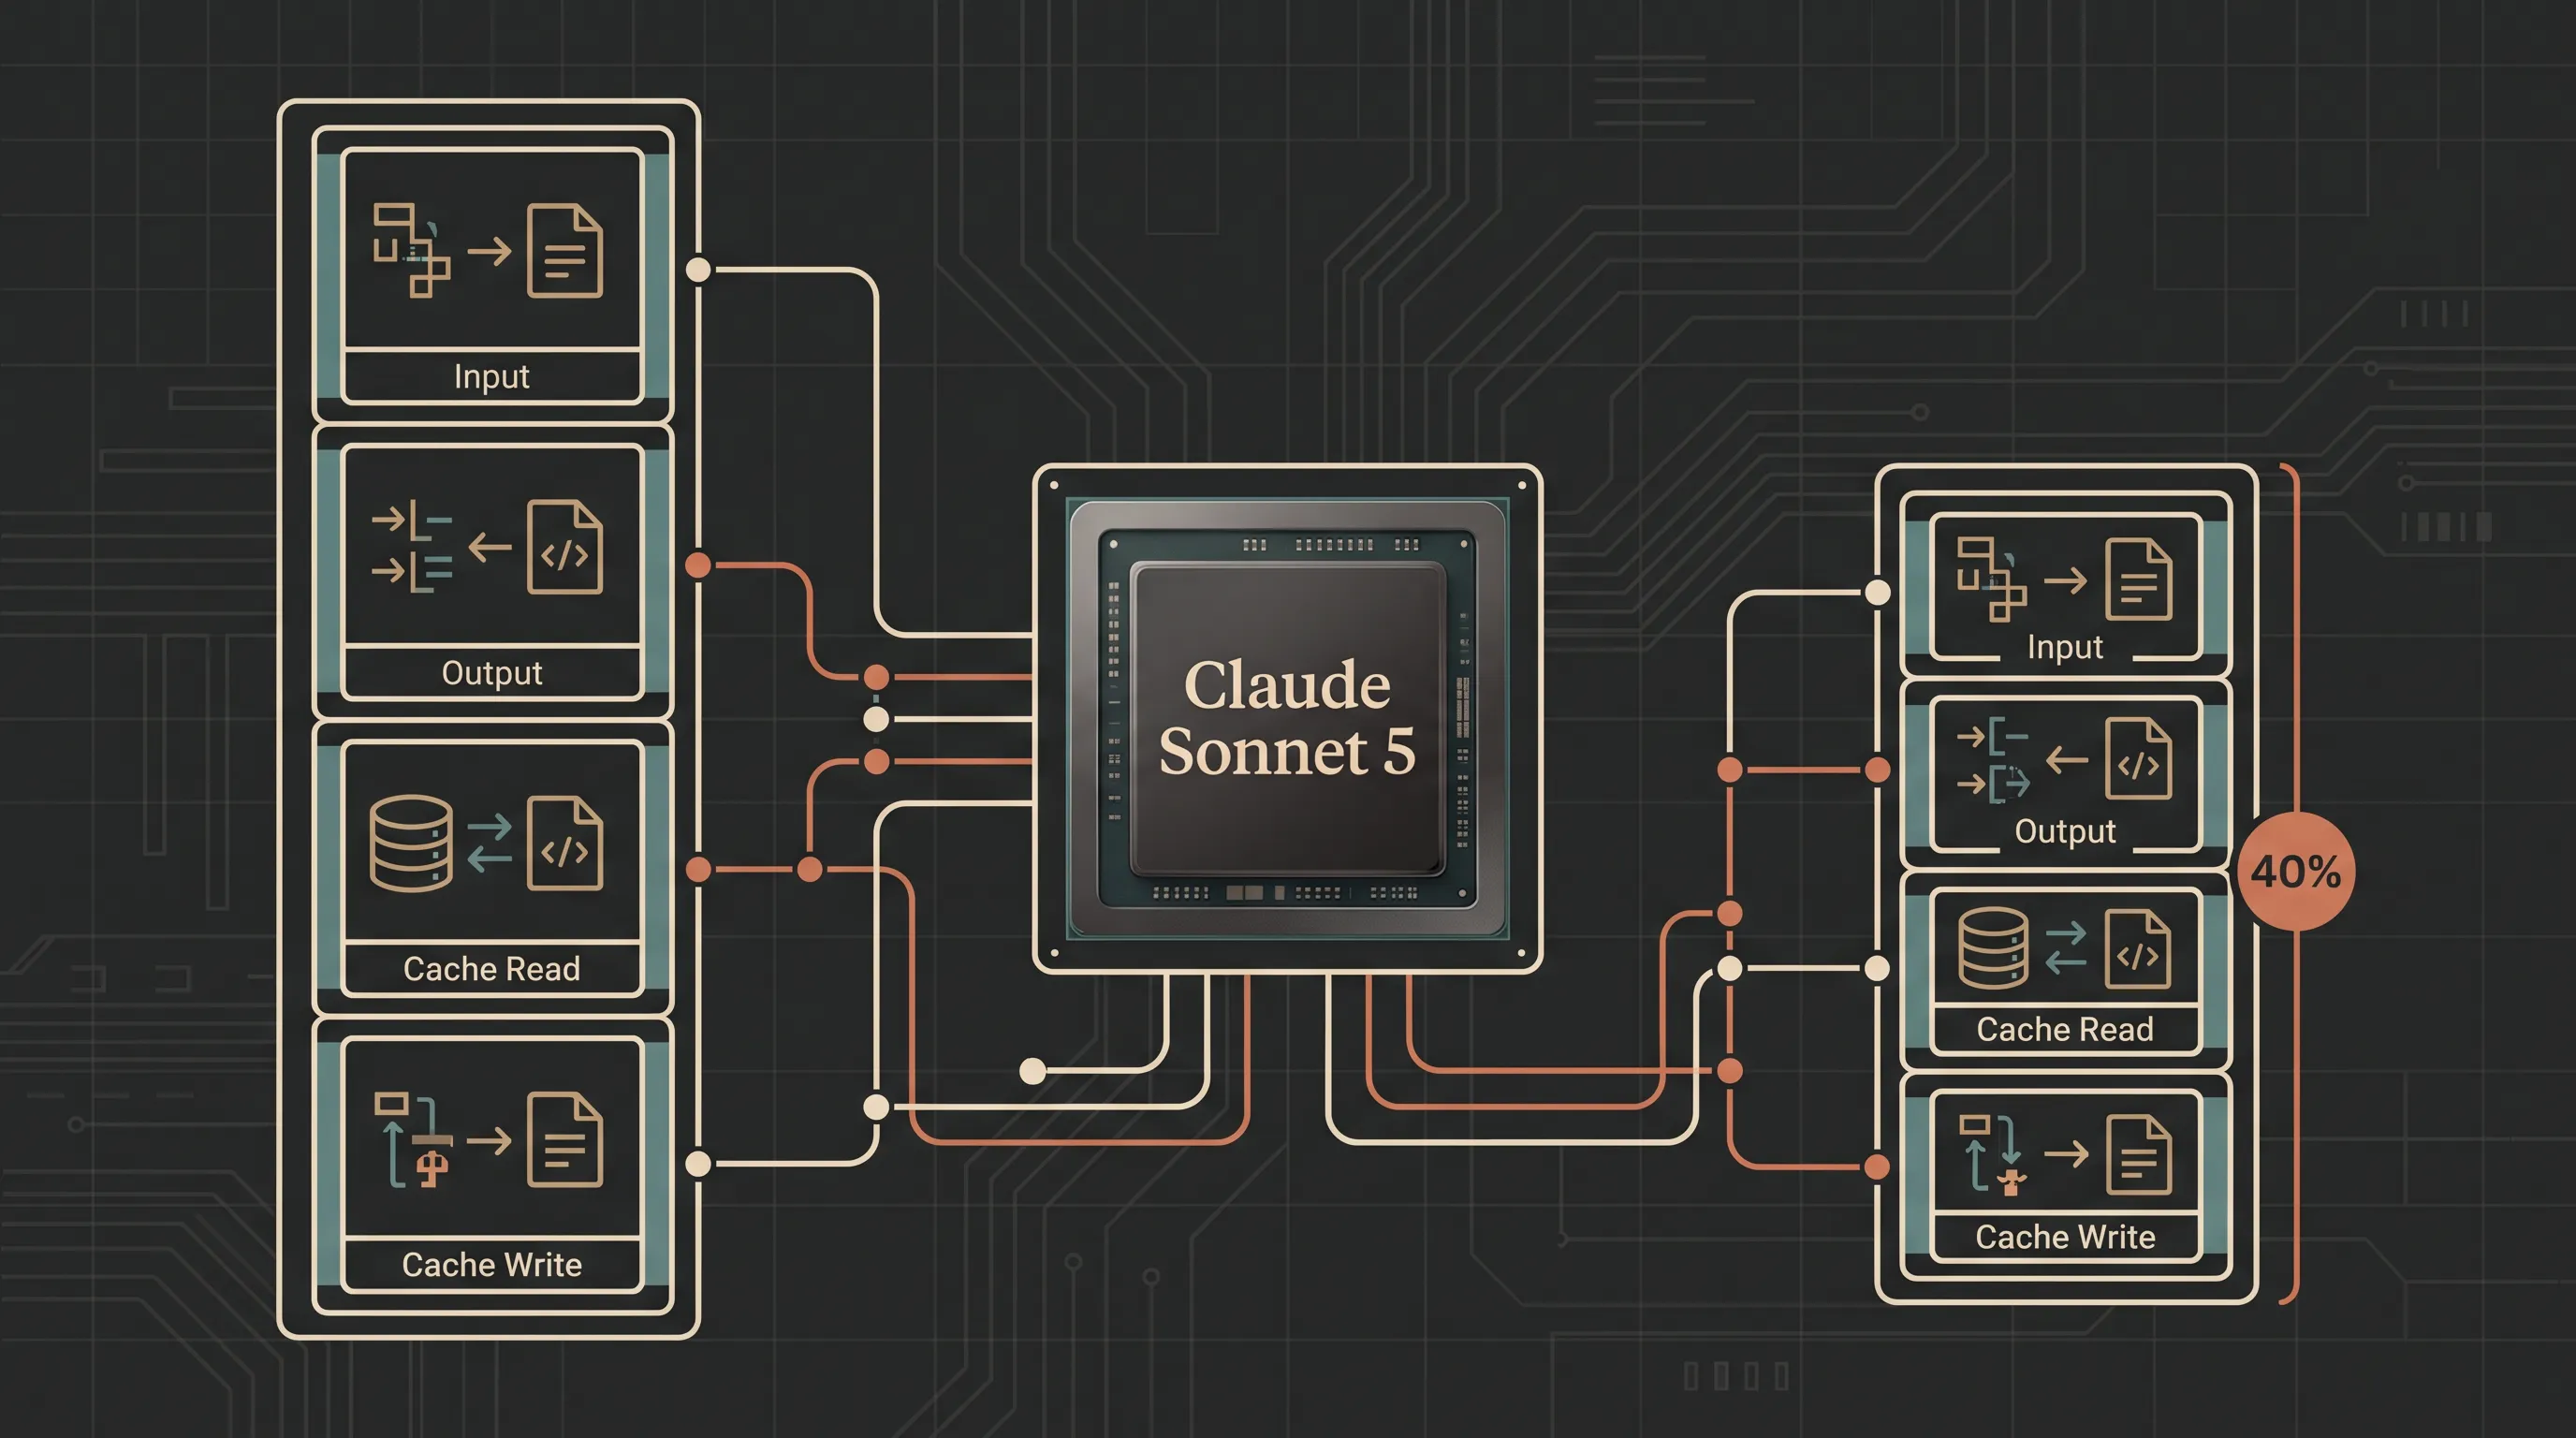
Claude Sonnet 5 launched on June 30, 2026, at $2 per million input tokens and $10 per million output tokens — the same per-token pricing that made Sonnet 4 the default daily driver for thousands of teams. What sets Sonnet 5 apart is not just the price: it brings 1M-token context, 128K-token output, adaptive thinking, and agentic tool use that closes the gap with Opus on real-world coding and planning tasks.
This guide covers every rate on the official card, the levers that change your effective cost (prompt caching, batch, thinking tokens, and effort levels), worked cost scenarios you can verify yourself, and the third-party route that runs Sonnet 5 at 40 % of the official price without changing a line of code.
| Official (Anthropic) | OurToken (40 % route) | |
|---|---|---|
| Input | $2.00 / MTok | $0.80 / MTok |
| Output | $10.00 / MTok | $4.00 / MTok |
| Cache read | $0.20 / MTok | $0.08 / MTok |
| Cache write (5 min) | $2.50 / MTok | $1.00 / MTok |
| Monthly savings | — | ~60 % |
Bottom line: switch your base URL from
api.anthropic.comtoapi.ourtoken.aiand cut your Sonnet 5 bill by 60 % with zero code changes.
Claude Sonnet 5 Pricing: The Official Rate Card
The table below lists every pricing category Anthropic publishes for Sonnet 5, with the corresponding rate on OurToken (the unified API at 40 % of official pricing).
| Token category | Official rate ($/M tok) | OurToken rate ($/M tok) | Keystone |
|---|---|---|---|
| Input (standard) | 2.00 | 0.80 | 40 % of official |
| Output (standard) | 10.00 | 4.00 | 40 % of official |
| Prompt cache write (5 min TTL) | 2.50 | 1.00 | 40 % of official |
| Prompt cache write (1 hour TTL) | 4.00 | 1.60 | 40 % of official |
| Cache hits (reads) | 0.20 | 0.08 | 40 % of official |
| Batch API input | 1.00 | n/a — OurToken standard rate is lower than Anthropic batch | |
| Batch API output | 5.00 | n/a — same logic applies |
A few notes that matter for your budget:
Cache hits cost one‑tenth of standard input. This is the single biggest lever on the card. Repeat the same system prompt or repo context and the tenth call costs you $0.20/M instead of $2.00/M.
Batch is flat 50 % off both input and output through Anthropic's own endpoint. Through a third‑party provider that does not offer batch, the standard rate may still match or beat Anthropic's batch price — run the arithmetic on your actual token mix.
There is no long‑context premium. Every token inside the 1M context window bills at the same rate. A 200k prompt costs the same per token as a 500k prompt.
Note on introductory pricing. The $2/$10 rates above were the introductory price through August 31, 2026. The current standard pricing from Anthropic is $3 per million input tokens and $15 per million output tokens. OurToken's rate adjusts proportionally: $1.20/M input and $6.00/M output — still 40 % of whatever Anthropic charges. All calculations in this guide use the introductory $2/$10 rates, which remain the most widely cited reference for Sonnet 5 pricing.
Where the rate card is misleading
The table above implies a linear model: send N tokens, get billed N × rate. In practice the final bill depends on three invisible factors that no rate card shows:
-
Thinking tokens bill as output. Sonnet 5 enables adaptive thinking by default. The reasoning tokens the model generates internally before producing its visible answer are charged at the output rate. Two identical‑looking conversations can have very different thinking depths and therefore very different output token counts.
-
Verbosity changes the token count, not the rate. Sonnet 5 is faster and more concise than Opus 5 on routine tasks, but on complex agentic traces it can still generate significant thinking overhead. Always check the
usageblock in the response rather than estimating from visible output. -
Effort levels are a dial your engineers control. Sonnet 5 supports
low,medium,high, andmaxeffort levels. Flipping from medium to max effort is a single configuration flag that changes your unit economics, and no invoice line will tell you it happened.
Why Your Sonnet 5 Bill Is Not the Sticker Price
The simplest way to see the gap between sticker and bill is to compare the same task on two rate cards.
| Factor | Official standard | Official with cache & batch | OurToken standard | OurToken with cache |
|---|---|---|---|---|
| Single 4k‑in / 800‑out chat call | $0.0160 | — | $0.0064 | — |
| 30‑turn agent session (90k prefix) | $5.91 | $1.26 | $2.37 | $0.50 |
| Batch enrichment (30M in / 3M out) | $90.00 | $45.00 | $36.00 | — |
The numbers in each row are real (we work through the arithmetic below). The takeaway: even the most aggressive official configuration (cache + batch) can be undercut by a third‑party standard rate.
Thinking tokens are the hidden line item
When you call Sonnet 5 with the thinking parameter or when adaptive thinking is on,
the model generates internal reasoning tokens that never appear in content[].text but do appear in usage.output_tokens.
Those tokens bill at $10/M — the full output rate.
In practice, a 2k‑character visible answer can cost 4k–6k of billed output tokens once thinking is included.
Always check the usage block in the response rather than guessing from visible output length.
Effort levels change the cost per completion
Sonnet 5 exposes an effort parameter (low, medium, high, max).
Higher effort produces better answers on hard problems but uses significantly more thinking tokens.
low→ minimal reasoning, fast, cheap, good for simple Q&A and classificationmedium→ default, balanced cost‑quality ratiohigh→ deeper reasoning, useful for coding and planningmax→ frontier reasoning, expensive, use only for tasks that genuinely need it
The CLI argument or API parameter is one line of code;
the cost difference between low and max on the same prompt can be 3–5x.
How to Cut Claude Sonnet 5 Costs
Cache the prefix
Any repeated prefix — system prompt, repo context, few‑shot examples — should be wrapped in cache_control.
One cache write (at $2.50/M) saves you $1.80/M on every subsequent turn.
Practical rule: if the same text appears in three or more requests, cache it. The breakeven on a 5‑minute cache write is two reads (write $2.50 + two reads at $0.20 = $2.90 vs three standard inputs at $6.00 → $3.10 saved after three calls).
Batch what can wait
For classification, enrichment, evaluation, or any workload that tolerates asynchronous delivery, use Anthropic's Batch API. Batch is flat 50 % off and runs within 24 hours. Through a third‑party provider that does not offer batch, the standard rate may still match or beat Anthropic's batch price — run the arithmetic on your actual token mix.
Turn the effort dial down
Not every prompt needs deep reasoning.
Route summarization, extraction, and simple Q&A through Sonnet 5 at low or medium effort,
or better yet through a lighter model like Haiku for the cheapest possible throughput.
Route routine work to a cheaper model
Sonnet 5 is your daily driver for coding, agentic tasks, and complex knowledge work. Simple classification, fixed‑format extraction, and lightweight generation belong on Haiku. A model‑routing layer that sends cheap work to the cheap model and complex work to Sonnet 5 can cut your blended rate by 50–70 % without users noticing the difference. LLM model routing covers the implementation in detail.
Worked Claude Sonnet 5 Cost Scenarios
Each scenario below shows the arithmetic on both rate cards so you can verify every number.
Scenario 1: a single chat completion (4k in / 800 out)
A typical chat or Q&A call with 4,000 input tokens and 800 output tokens.
Official cost per call: $0.0160 → OurToken cost per call: $0.0064 (save $0.0096).
| Line item | Official | OurToken |
|---|---|---|
| Input: 4,000 / 1,000,000 × rate | 0.004 × $2.00 = $0.0080 | 0.004 × $0.80 = $0.0032 |
| Output: 800 / 1,000,000 × rate | 0.0008 × $10.00 = $0.0080 | 0.0008 × $4.00 = $0.0032 |
| Total per call | $0.0160 | $0.0064 |
At 50,000 calls per month:
- Official: $800.00
- OurToken: $320.00
- Savings: $480.00 (60 %)
Scenario 2: a 30‑turn coding agent session with prompt caching
A coding assistant maintains a 90,000‑token system prompt plus repo context and runs 30 turns. Each turn adds 1,000 new conversation tokens and produces 1,500 output tokens.
Official uncached: $5.91/session → official cached: $1.26/session → OurToken cached: $0.50/session (save $5.41 vs uncached).
Without cache (official): 30 turns resend the full prefix each time.
| Line item | Tokens | Rate | Cost |
|---|---|---|---|
| Input (90k × 30 + 30k) | 2,730,000 | $2.00 | $5.46 |
| Output (1.5k × 30) | 45,000 | $10.00 | $0.45 |
| Total | $5.91 |
With 5‑minute cache (official): one cache write, then 29 cache reads.
| Line item | Tokens | Rate | Cost |
|---|---|---|---|
| Cache write (once) | 90,000 | $2.50 | $0.225 |
| Cache reads (29 × 90k) | 2,610,000 | $0.20 | $0.522 |
| New input (1k × 30) | 30,000 | $2.00 | $0.06 |
| Output (1.5k × 30) | 45,000 | $10.00 | $0.45 |
| Total | $1.257 |
With cache (OurToken): same token counts at 40 % of each official rate.
| Line item | Tokens | Rate | Cost |
|---|---|---|---|
| Cache write (once) | 90,000 | $1.00 | $0.09 |
| Cache reads (29 × 90k) | 2,610,000 | $0.08 | $0.2088 |
| New input (1k × 30) | 30,000 | $0.80 | $0.024 |
| Output (1.5k × 30) | 45,000 | $4.00 | $0.18 |
| Total | $0.5028 |
Per‑session comparison:
- Official uncached: $5.91
- Official cached: $1.26
- OurToken cached: $0.50
- OurToken cached is 60 % cheaper than official cached and 91 % cheaper than official uncached.
Scenario 3: a batch enrichment job (30M in / 3M out)
Process 25,000 documents, each requiring 1,200 input tokens and 120 output tokens. Total volume: 30,000,000 input tokens (30 MTok) and 3,000,000 output tokens (3 MTok).
Official batch: $45.00 → OurToken standard: $36.00 — OurToken is already cheaper than Anthropic batch, with no latency trade-off.
| Configuration | Input cost | Output cost | Total |
|---|---|---|---|
| Official standard | 30 × $2.00 = $60.00 | 3 × $10.00 = $30.00 | $90.00 |
| Official batch (50 % off) | 30 × $1.00 = $30.00 | 3 × $5.00 = $15.00 | $45.00 |
| OurToken standard (40 %) | 30 × $0.80 = $24.00 | 3 × $4.00 = $12.00 | $36.00 |
OurToken's standard rate ($36.00) is already 20 % cheaper than Anthropic's batch rate ($45.00), with no latency trade‑off.
Monthly rollup: the same workload on two rate cards
Combine the three scenarios into a typical team's monthly spend.
Official monthly total: $1,520.00 → OurToken monthly total: $606.00 → save $914.00 (60.1 %).
| Workload | Volume | Official monthly | OurToken monthly |
|---|---|---|---|
| Chat completions (scenario 1) | 50,000 calls | $800.00 | $320.00 |
| Agent sessions (scenario 2) | 500 sessions | 500 × $1.26 = $630.00 | 500 × $0.50 = $250.00 |
| Enrichment job (scenario 3) | 30M/3M tok | $90.00 | $36.00 |
| Total | $1,520.00 | $606.00 | |
| Savings | $914.00 (60 %) |
Verification: $1,520.00 − $606.00 = $914.00. $914.00 / $1,520.00 = 0.6013 ≈ 60.1 %.
Running Sonnet 5 Through One Compatible Endpoint
You do not need separate routing code for every provider.
A unified API endpoint accepts the same messages payload,
the same Model ID claude-sonnet-5, and the same cache_control markers
while billing at 40 % of the official rate.
┌──────────────────────┐
│ Your Application     │
│ (SDK, cURL, Python)  │
└──────┬───────────────┘
       │ POST /v1/messages
       │ Authorization: Bearer YOUR_API_KEY
       │ {"model":"claude-sonnet-5",...}
       ▼
┌──────────────────────────────────┐
│ api.ourtoken.ai/v1/messages      │
│ Base URL: https://api.ourtoken.ai/v1
│ Model ID: claude-sonnet-5         │
│ Pricing: 40 % of official         │
└──────────────────────────────────┘
cURL smoke test
curl https://api.ourtoken.ai/v1/messages \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $OURTOKEN_API_KEY" \
  -d '{
  "model": "claude-sonnet-5",
  "max_tokens": 256,
  "messages": [
    {"role": "user", "content": "Estimate the cost of 4k in / 800 out tokens on Sonnet 5."}
  ]
}'
The response includes a usage object with input_tokens, output_tokens,
cache_creation_input_tokens, and cache_read_input_tokens.
Multiply by your rate and log every call for budget tracking.
Python: estimate cost before you ship
"""Cost estimator for Claude Sonnet 5 — official vs third‑party rates."""

RATES = {
    "official": {
        "input": 2.00, "output": 10.00,
        "cache_write": 2.50, "cache_read": 0.20,
    },
    "ourtoken": {
        "input": 0.80, "output": 4.00,
        "cache_write": 1.00, "cache_read": 0.08,
    },
}


def estimate_cost(
    input_tokens: int,
    output_tokens: int,
    cache_write_tokens: int = 0,
    cache_read_tokens: int = 0,
    calls: int = 1,
    rate_card: str = "official",
) -> float:
    r = RATES[rate_card]
    per_call = (
        input_tokens / 1_000_000 * r["input"]
        + output_tokens / 1_000_000 * r["output"]
        + cache_write_tokens / 1_000_000 * r["cache_write"]
        + cache_read_tokens / 1_000_000 * r["cache_read"]
    )
    return round(per_call * calls, 4)


if __name__ == "__main__":
    # Scenario 1 — single call
    off = estimate_cost(4000, 800, rate_card="official")
    ot = estimate_cost(4000, 800, rate_card="ourtoken")
    print(f"Single call — official: ${off:.4f}, ourtoken: ${ot:.4f}")

    # Scenario 2 — agent session with cache
    off2 = estimate_cost(30000, 45000, cache_write_tokens=90000,
                         cache_read_tokens=2610000, rate_card="official")
    ot2 = estimate_cost(30000, 45000, cache_write_tokens=90000,
                        cache_read_tokens=2610000, rate_card="ourtoken")
    print(f"Agent session — official: ${off2:.2f}, ourtoken: ${ot2:.2f}")

    # Scenario 3 — batch-equivalent
    off3 = estimate_cost(30_000_000, 3_000_000, rate_card="official")
    ot3 = estimate_cost(30_000_000, 3_000_000, rate_card="ourtoken")
    print(f"Enrichment job — official: ${off3:.2f}, ourtoken: ${ot3:.2f}")
Python: call the API with retry and usage logging
Below is a concise production-ready snippet. For the full version with configurable backoff, timeout, and batch logging, download the complete example.
import json, os, time, urllib.request

def call_sonnet_5(prompt: str, max_tokens: int = 1024) -> dict:
    api_key = os.environ["OURTOKEN_API_KEY"]
    body = json.dumps({"model": "claude-sonnet-5", "max_tokens": max_tokens,
                       "messages": [{"role": "user", "content": prompt}]}).encode()
    req = urllib.request.Request(
        "https://api.ourtoken.ai/v1/messages",
        data=body, headers={"Content-Type": "application/json",
                            "Authorization": f"Bearer {api_key}"})
    for attempt in range(3):
        try:
            with urllib.request.urlopen(req, timeout=60) as resp:
                return json.loads(resp.read().decode())
        except urllib.error.HTTPError as e:
            if e.code in (429, 502, 503) and attempt < 2:
                time.sleep(2 ** attempt)
                continue
            raise

result = call_sonnet_5("Compare the cost of 4k input tokens on Sonnet 5.")
print(json.dumps(result.get("usage", {}), indent=2))
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Bill is higher than cost estimator predicted | Thinking tokens bill as output | Reduce effort level or cap max_tokens |
| Cache hits never appear in the usage block | 5‑minute TTL expired between turns | Use 1‑hour cache write or keep session turns within 5 minutes |
| Output tokens dominate the bill | High verbosity on agentic traces | Route simple work to a lighter model or reduce effort level |
401 response on /v1/messages | Wrong API key or missing Bearer prefix | Generate a new key at /api-keys |
| Model responds but discount rate is not reflected | Rate card referenced an outdated date | Check the live /models/anthropic/claude-sonnet-5 page |
temperature / top_p returns a 400 error | Sonnet 5 does not support non-default sampling params | Remove temperature, top_p, and top_k from the request body |
Conclusion
Claude Sonnet 5 pricing is straightforward to read and easy to mis‑budget. The official rate card says $2/$10, but the real cost per completion depends on effort level, thinking depth, cache configuration, and whether you batch. The most expensive way to use Sonnet 5 is to call each turn without caching at max effort. The cheapest official way combines prompt caching and batch — but even that can be undercut by a unified API that charges 40 % of the official rate.
If your team already writes to the messages endpoint, switching the base URL
from https://api.anthropic.com/v1 to https://api.ourtoken.ai/v1 is a one‑line change
that drops your Sonnet 5 bill by 60 %.
The same model ID, the same cache_control markers, the same usage response structure.
You keep every data integrity check you already have. Get a free key with $5 in initial credit to verify the math against your own traffic.
FAQ
What is the exact price of Claude Sonnet 5 per million tokens?
The introductory price (through August 31, 2026) is $2.00 per million input tokens and $10.00 per million output tokens. The current standard pricing is $3.00/M input and $15.00/M output. Cache reads cost $0.20/M ($0.30/M at standard), cache writes cost $2.50/M ($3.75/M at standard) for 5‑minute TTL or $4.00/M ($6.00/M at standard) for 1‑hour TTL. Batch API prices are 50 % off: $1.00/M ($1.50/M) input and $5.00/M ($7.50/M) output.
How does OurToken's Sonnet 5 price compare to Anthropic's?
OurToken charges $0.80/M input and $4.00/M output — exactly 40 % of the introductory official rate. Cache reads are $0.08/M, cache writes $1.00/M. No minimum, no commitment. If Anthropic moves to standard pricing, OurToken adjusts proportionally, maintaining the 40 % discount.
Does Sonnet 5 cost more than Sonnet 4?
Sonnet 5 maintains the same per‑token rate as Sonnet 4 ($2/$10 introductory). The key difference is that Sonnet 5's adaptive thinking may produce more output tokens per completion on complex tasks, but the rate per million tokens on the invoice is identical.
What is Sonnet 5 batch pricing?
Anthropic's Batch API cuts the standard rate in half: $1.00/M input and $5.00/M output (introductory). Through OurToken, the standard rate ($0.80/$4.00) is already below Anthropic's batch price — you save without sacrificing synchronous response time.
Does prompt caching actually reduce the bill?
Yes. A cache read costs $0.20/M instead of $2.00/M, a 90 % discount on every cached input token. In agentic sessions that repeat the same system prompt across multiple turns, prompt caching can cut the cost by 70–80 %. See the prompt caching guide for implementation patterns.
What is the cheapest way to use Claude Sonnet 5?
Combine prompt caching for repeated prefixes, batch for asynchronous jobs, set effort to medium by default (raise to high or max only on hard problems), and route through a 40 % provider. The cheapest arch is also the simplest: one endpoint, one API key, one rate card.
Can I use Sonnet 5 for real‑time user‑facing applications?
Yes. Sonnet 5 is Anthropic's fastest frontier model — it delivers the first token faster than Opus 5 and is well‑suited for chat, code review, interactive agentic sessions, and any latency‑sensitive workload. Unlike Opus, Sonnet 5 does not offer a fast mode tier because its standard speed is already competitive for real‑time use.
Does Sonnet 5 support temperature and top_p?
No. Sonnet 5 requires default values for temperature, top_p, and top_k. Setting these to non‑default values returns a 400 error. This is by design — Anthropic fixed the sampling parameters to ensure consistent adaptive thinking behavior. Remove these fields from your request body when switching to Sonnet 5.