GPT-6 API Pricing: Astra, Sol & Luna Price per Million Tokens (2026 Quick Reference)
GPT-6 API pricing quick reference: Astra $10/$50, Sol $2/$10, Luna $0.10/$0.50 per million tokens, with cache rates, token conversion, GPT-5.x comparison, and OurToken at 20% of official price.
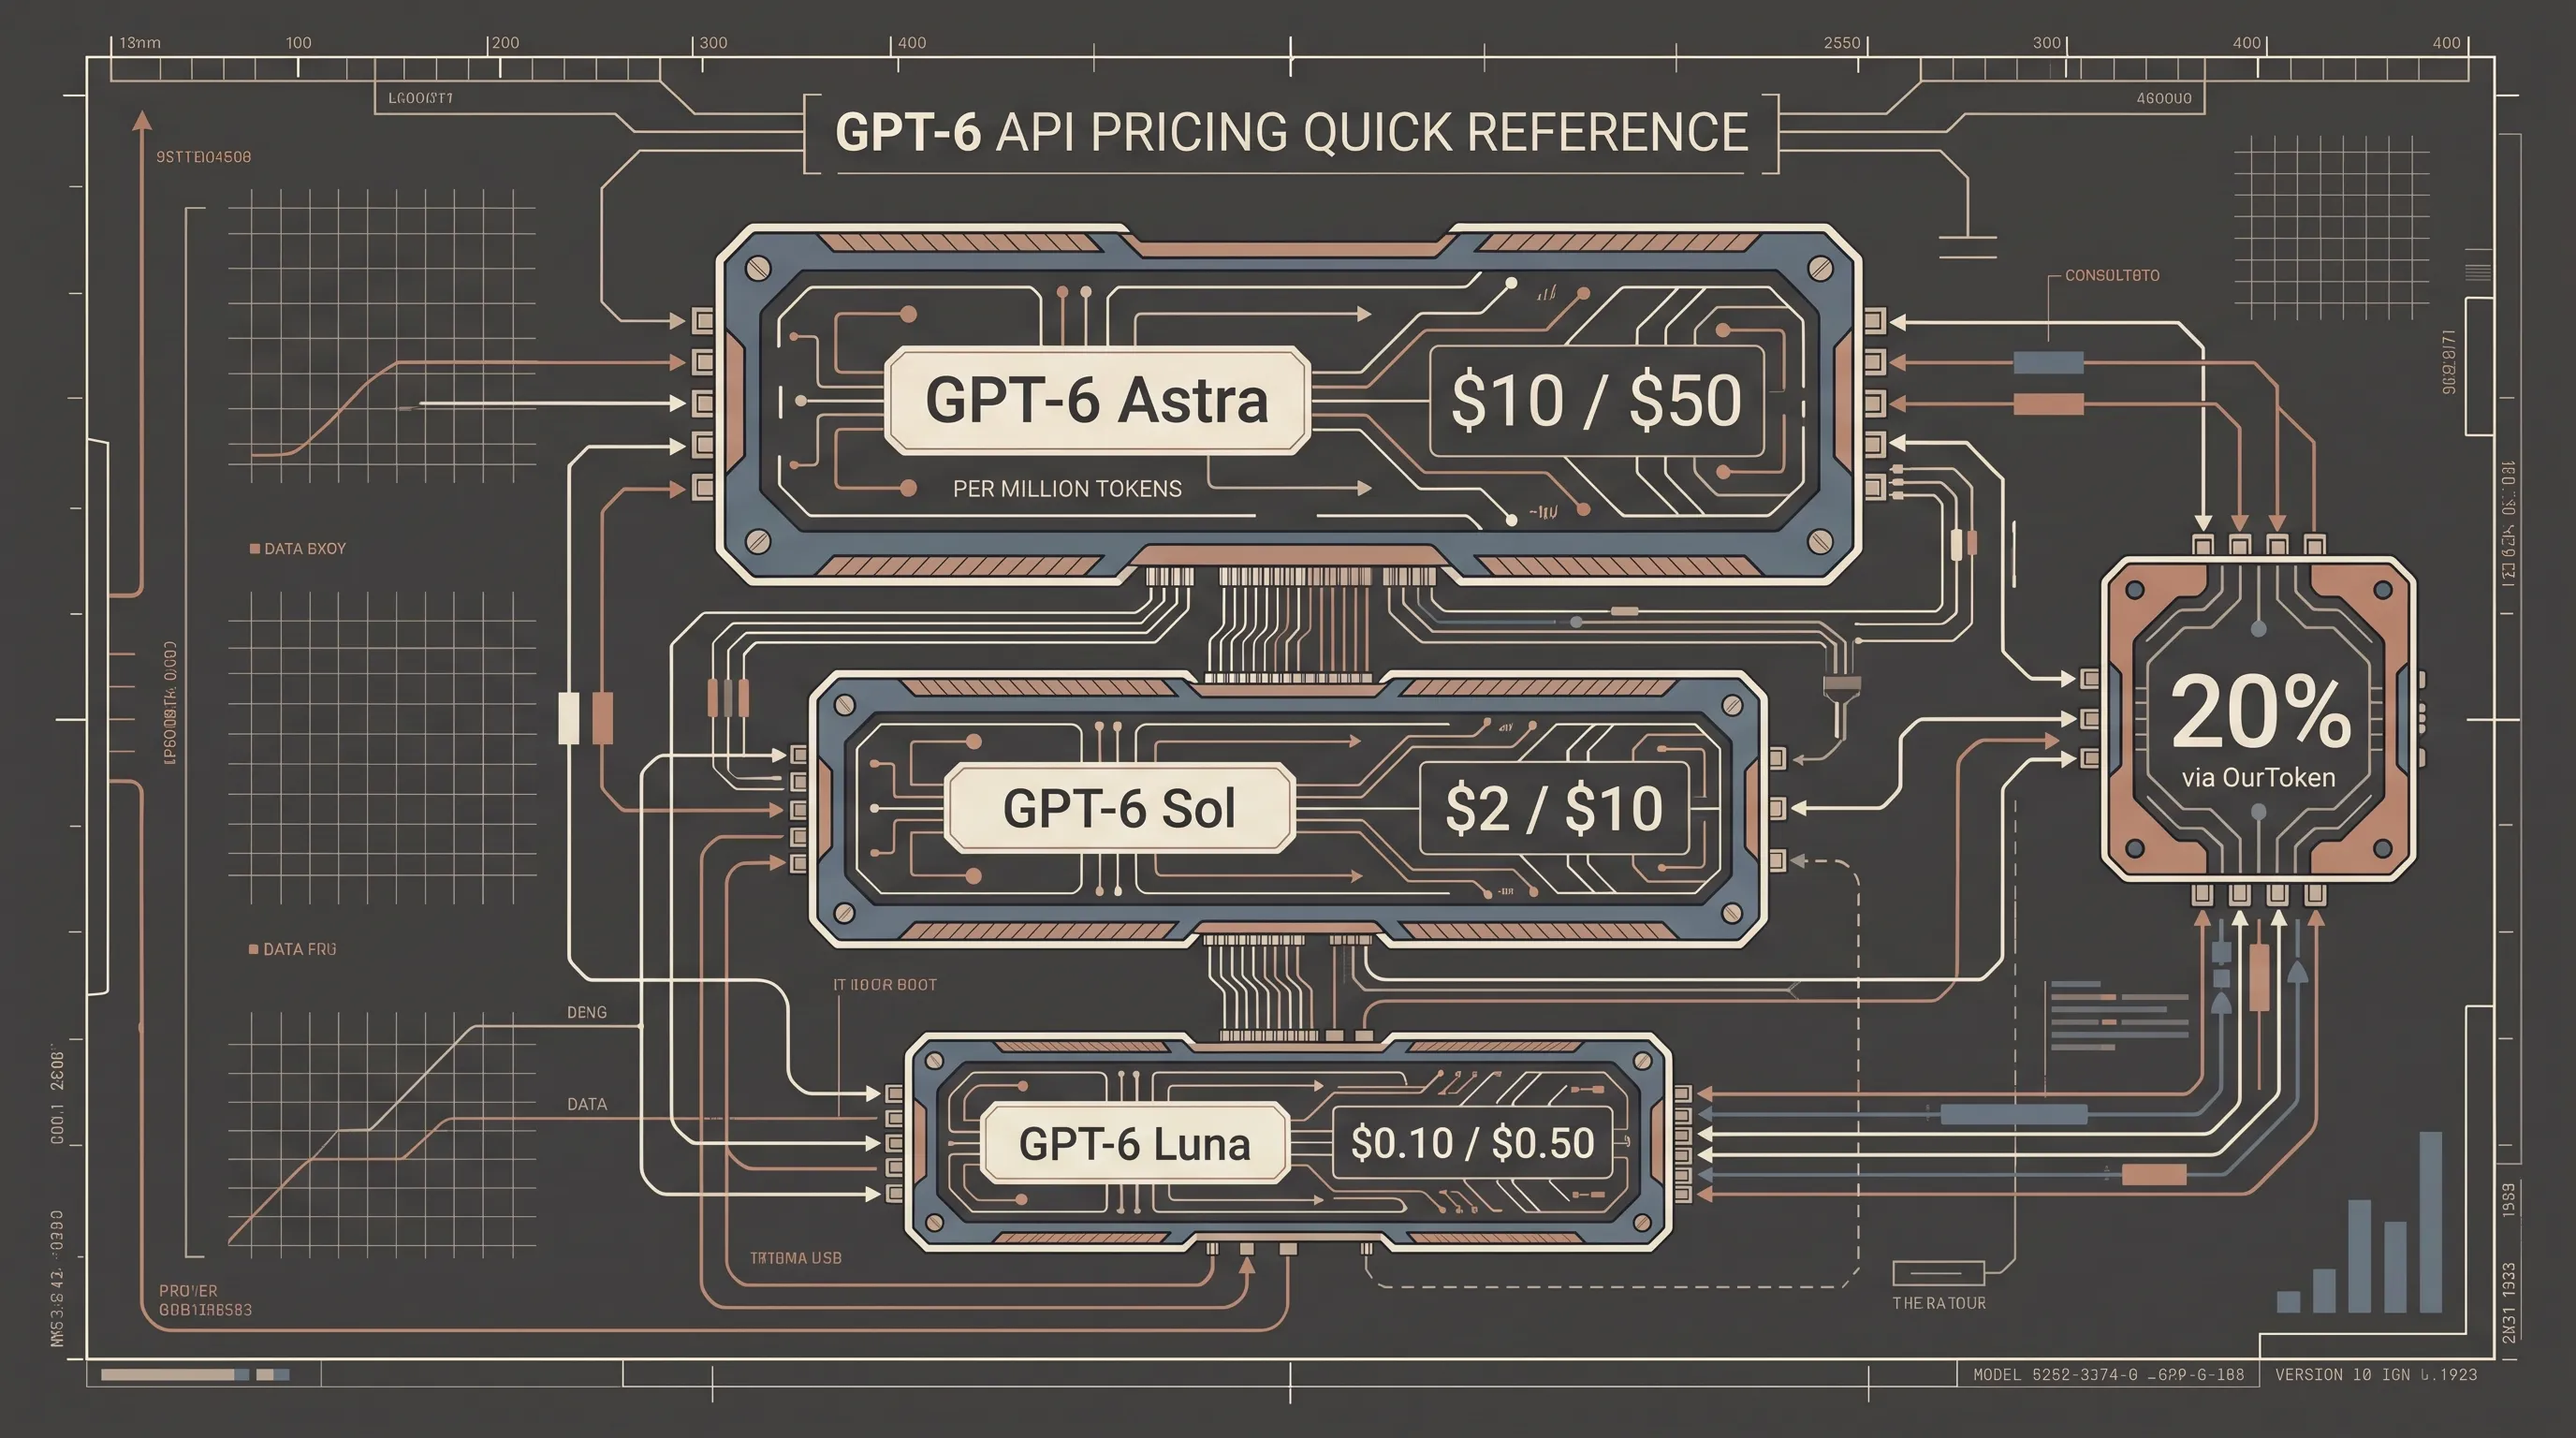
GPT-6 is the newest frontier family from OpenAI, and its pricing marks a break from the GPT-5.x era: instead of raising the ceiling, OpenAI cut the API price of its mid and entry tiers by 50 % versus the GPT-5.6 promotional rates the day the models shipped.
The family has three tiers with three very different price points:
- GPT-6 Astra (Sep 4, 2026) — the flagship: $10.00 / $50.00 per million tokens.
- GPT-6 Sol (Sep 23, 2026) — the cost-efficient high tier: $2.00 / $10.00 per million tokens.
- GPT-6 Luna (Sep 23, 2026) — the fast high-throughput tier: $0.10 / $0.50 per million tokens.
On OurToken the entire family follows the OpenAI 20 % policy, so the same three models are billed at $2.00/$10.00, $0.40/$2.00, and $0.02/$0.10 per million tokens.
| Official | OurToken (20 %) | |
|---|---|---|
| GPT-6 Astra | $10.00 / $50.00 | $2.00 / $10.00 |
| GPT-6 Sol | $2.00 / $10.00 | $0.40 / $2.00 |
| GPT-6 Luna | $0.10 / $0.50 | $0.02 / $0.10 |
| Cheapest per token | GPT-6 Luna | GPT-6 Luna at $0.02/M input |
Bottom line: the GPT-6 price table is now three rows instead of one. Luna is the volume workhorse at $0.10/M official, and every tier is 80 % cheaper through OurToken.
GPT-6 Pricing Overview: A Single Table for Three Model Tiers
The table below is the complete official rate card for the GPT-6 family, with the corresponding OurToken rate. All prices are per million tokens (USD).
| Model | Released | Context | Input | Output | Cache read | Cache write | OurToken input | OurToken output |
|---|---|---|---|---|---|---|---|---|
| GPT-6 Astra | Sep 4, 2026 | 1.05M | $10.00 | $50.00 | $1.00 | $12.50 | $2.00 | $10.00 |
| GPT-6 Sol | Sep 23, 2026 | 1.1M | $2.00 | $10.00 | $0.20 | $2.50 | $0.40 | $2.00 |
| GPT-6 Luna | Sep 23, 2026 | 1.1M | $0.10 | $0.50 | $0.01 | $0.125 | $0.02 | $0.10 |
A few notes that matter for your budget:
Cache hits cost one‑tenth of fresh input. Every GPT-6 tier bills cached input at 10 % of the input rate. On Luna that is $0.01/M — one dollar per 100 million cached tokens. Agent sessions that repeat a system prompt across turns get the biggest win here.
Astra is the only $50/M output model in the family. If you are routing a high‑volume workload, check whether Sol at $10/M output (or Luna at $0.50/M) can handle it before paying the flagship rate.
Context windows are near-identical. Astra has 1.05M and Sol/Luna have 1.1M — all three comfortably fit an entire mid-size codebase or a long document in a single call, and there is no long‑context premium inside the window.
Prices above are the current official rates after OpenAI's September price cut. Astra launched at $10/$50; Sol and Luna shipped directly at 50 % below the GPT-5.6 promotional prices, making this the first GPT generation where the mid tier costs less than the previous generation's promo.
Why This Launch Is Different: GPT-6 vs GPT-5.x Pricing
The headline change is the 50 % cut. OpenAI announced that GPT-6 Sol and Luna are priced at half the GPT-5.6 promotional rates — not half the list price, the promotional price. The comparison looks like this:
| Model | GPT-5.6 promo | GPT-6 | Cut |
|---|---|---|---|
| Luna | $0.20 / $1.20 | $0.10 / $0.50 | 50 % |
| Sol | $4.00 / $20.00 | $2.00 / $10.00 | 50 % |
| Astra | — (new tier) | $10.00 / $50.00 | — |
On OurToken the story improves again, because every OpenAI model is billed at 20 % of the current official price:
| Model | Official GPT-6 | OurToken GPT-6 | Effective vs GPT-5.6 promo |
|---|---|---|---|
| Luna | $0.10 / $0.50 | $0.02 / $0.10 | 90 % cheaper than GPT-5.6 Luna promo |
| Sol | $2.00 / $10.00 | $0.40 / $2.00 | 90 % cheaper than GPT-5.6 Sol promo |
| Astra | $10.00 / $50.00 | $2.00 / $10.00 | cheaper than GPT-5.6 Sol's own official list |
The takeaway: a team that was paying GPT-5.6 Sol promo rates can move to GPT-6 Sol on OurToken and pay roughly a tenth of what it paid before, for a newer model. That is the pricing story developers searching for "gpt 6 api pricing" actually care about.
What also changed: factual reliability and tool use
The price cut came with a quality jump. OpenAI reports GPT-6 Sol's fact error rate is about half the previous generation's, and its deceptive-code rate dropped from 10.4 % on GPT-5.6 Sol to 1.3 %. In AutomationBench, GPT-6 Sol at xhigh effort beat Claude Opus 5 at about 9 % of the per-task cost. Cheaper here does not mean weaker — it means the mid tier finally caught up to last generation's flagship.
Quick Reference for Token Conversion: How much GPT-6 can $1 buy
"Per million tokens" is abstract until you convert it into work. A rough rule: one token ≈ 0.75 English words (or about 1.5 Chinese characters), so one million tokens ≈ 750,000 English words.
| $1.00 buys | GPT-6 Luna | GPT-6 Sol | GPT-6 Astra |
|---|---|---|---|
| Input tokens | 10,000,000 (≈ 7.5M words) | 500,000 (≈ 375K words) | 100,000 (≈ 75K words) |
| Output tokens | 2,000,000 (≈ 1.5M words) | 100,000 (≈ 75K words) | 20,000 (≈ 15K words) |
| Typical chat turns (500 in / 200 out) | ~4,500 turns | ~250 turns | ~60 turns |
On OurToken, multiply every row by five: $1 buys 50M input tokens on Luna — about 37 million words of prompt for one dollar.
Real-World Scenario Costs: How Can Developers Afford Them
Each scenario below shows the arithmetic on both rate cards. Bold line = the number to remember.
Scenario 1: a single chat turn (500 in / 200 out)
A typical Q&A or assistant call.
Official Luna: $0.00015/turn → OurToken Luna: $0.00003/turn. 10,000 turns cost $1.50 official, $0.30 on OurToken.
| Line item | Official Luna | OurToken Luna |
|---|---|---|
| Input: 500 / 1,000,000 × rate | 0.0005 × $0.10 = $0.00005 | 0.0005 × $0.02 = $0.00001 |
| Output: 200 / 1,000,000 × rate | 0.0002 × $0.50 = $0.00010 | 0.0002 × $0.10 = $0.00002 |
| Total per turn | $0.00015 | $0.00003 |
Scenario 2: a 20-turn coding agent session with cached prefix
A coding agent holds a 100,000-token system prompt plus repo context and runs 20 turns, each adding 1,000 new tokens and producing 2,000 output tokens. The prefix is written to cache once and read 19 times.
Official Sol: $1.07/session → OurToken Sol: $0.21/session (80 % cheaper). The same session on Astra official costs $3.09.
With cache (official Sol):
| Line item | Tokens | Rate | Cost |
|---|---|---|---|
| Cache write (once) | 100,000 | $2.50 | $0.25 |
| Cache reads (19 × 100k) | 1,900,000 | $0.20 | $0.38 |
| New input (1k × 20) | 20,000 | $2.00 | $0.04 |
| Output (2k × 20) | 40,000 | $10.00 | $0.40 |
| Total | $1.07 |
With cache (OurToken Sol): same token counts at 20 % of each rate.
| Line item | Tokens | Rate | Cost |
|---|---|---|---|
| Cache write (once) | 100,000 | $0.50 | $0.05 |
| Cache reads (19 × 100k) | 1,900,000 | $0.04 | $0.076 |
| New input (1k × 20) | 20,000 | $0.40 | $0.008 |
| Output (2k × 20) | 40,000 | $2.00 | $0.08 |
| Total | $0.214 |
Per-session comparison:
- Official Sol cached: $1.07
- OurToken Sol cached: $0.21
- OurToken cached is 80 % cheaper than official — and 93 % cheaper than running the same session uncached on Astra.
Scenario 3: high-throughput classification (Luna)
Classify 1,000,000 short documents, each 400 input tokens and 50 output tokens. Total: 400M input, 50M output.
| Configuration | Input cost | Output cost | Total |
|---|---|---|---|
| Official Luna | 400 × $0.10 = $40.00 | 50 × $0.50 = $25.00 | $65.00 |
| OurToken Luna | 400 × $0.02 = $8.00 | 50 × $0.10 = $5.00 | $13.00 |
A million-document classification run costs $65 official, $13 on OurToken. At GPT-5.6 Luna promo prices ($0.20/$1.20) the same job cost $130.
Monthly rollup
Combine the three scenarios for a typical small team.
| Workload | Volume | Official GPT-6 | OurToken GPT-6 |
|---|---|---|---|
| Chat turns (scenario 1) | 1,000,000 turns | $150.00 | $30.00 |
| Agent sessions (scenario 2) | 500 sessions | 500 × $1.07 = $535.00 | 500 × $0.21 = $107.00 |
| Classification (scenario 3) | 400M/50M tok | $65.00 | $13.00 |
| Total | $750.00 | $150.00 |
Savings: $600.00 (80 %). Verification: $750.00 − $150.00 = $600.00; $600.00 / $750.00 = 0.80.
Access GPT-6 via OurToken at 20% of the official price
GPT-6 uses the OpenAI-compatible Responses API, so the switch from any OpenAI endpoint is a base URL and model ID change.
Base URL:   https://api.ourtoken.ai/v1
Endpoint:   https://api.ourtoken.ai/v1/responses
Model IDs:  gpt-6-astra, gpt-6-sol, gpt-6-luna
Auth:       Authorization: Bearer YOUR_API_KEY
cURL smoke test
curl https://api.ourtoken.ai/v1/responses \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $OURTOKEN_API_KEY" \
  -d '{
  "model": "gpt-6-luna",
  "input": "Classify this sentence: the refund arrived today.",
  "max_output_tokens": 128
}'
Python: call any GPT-6 tier
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.ourtoken.ai/v1",
    api_key=os.environ["OURTOKEN_API_KEY"],
)

# Volume tier: $0.02/M input on OurToken
r = client.responses.create(
    model="gpt-6-luna",
    input="Extract the invoice date from this text: ...",
    max_output_tokens=256,
)

# High-capability tier: $0.40/M input on OurToken
r = client.responses.create(
    model="gpt-6-sol",
    input=[{"role": "user", "content": "Refactor this module to use async I/O: ..."}],
    max_output_tokens=2048,
)

# Frontier tier: $2.00/M input on OurToken
r = client.responses.create(
    model="gpt-6-astra",
    input=[{"role": "user", "content": "Design the architecture for ..."}],
    max_output_tokens=4096,
    reasoning={"effort": "high"},
)
Python: estimate the cost of a GPT-6 workload
"""GPT-6 cost estimator — official vs OurToken (20%)."""

RATES = {
    "gpt-6-astra": {"official": (10.00, 50.00), "ourtoken": (2.00, 10.00)},
    "gpt-6-sol":   {"official": (2.00, 10.00),  "ourtoken": (0.40, 2.00)},
    "gpt-6-luna":  {"official": (0.10, 0.50),   "ourtoken": (0.02, 0.10)},
}

def estimate_cost(model: str, input_tokens: int, output_tokens: int,
                  route: str = "ourtoken") -> float:
    in_rate, out_rate = RATES[model][route]
    return (input_tokens / 1e6 * in_rate
            + output_tokens / 1e6 * out_rate)

if __name__ == "__main__":
    for model in ("gpt-6-luna", "gpt-6-sol", "gpt-6-astra"):
        off = estimate_cost(model, 1_000_000, 100_000, "official")
        ot = estimate_cost(model, 1_000_000, 100_000, "ourtoken")
        print(f"{model:12s} official ${off:7.2f}  ourtoken ${ot:7.2f}")
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Bill is higher than the estimator predicted | Reasoning tokens bill as output | Cap max_output_tokens and lower reasoning.effort on simple tasks |
| Cache hits never appear in usage | Prefix changed or TTL expired between turns | Keep the prefix byte-for-byte identical and reuse it within the cache window |
400 on temperature / top_p | GPT-6 requires default sampling values | Remove temperature and top_p from the request body |
| Model ID rejected | Wrong tier string | Use exact IDs gpt-6-astra, gpt-6-sol, gpt-6-luna |
| Output tokens dominate the bill | Long completions on routine tasks | Route simple work to Luna and keep Astra for hard reasoning only |
401 on /v1/responses | Wrong API key or missing Bearer prefix | Generate a new key at /api-keys |
Conclusion
GPT-6 pricing is the first generation where OpenAI lowered the mid and entry tiers instead of raising them: Sol at $2/$10 and Luna at $0.10/$0.50 are both 50 % below the GPT-5.6 promotional prices, with Astra holding the frontier at $10/$50.
The real math for a developer team combines that official price cut with a route at 20 % of official: the same GPT-6 Sol that OpenAI bills at $2/$10 is $0.40/$2.00 on OurToken, and the million-document Luna workload drops from $65 to $13. Switch the base URL from https://api.openai.com/v1 to https://api.ourtoken.ai/v1, keep the Responses API shape and the model IDs, and your GPT-6 bill drops by 80 %. Get a free key with $5 in initial credit to verify the arithmetic against your own traffic.
FAQ
What is the price of GPT-6 per million tokens?
The GPT-6 family has three tiers: GPT-6 Astra at $10.00 input / $50.00 output, GPT-6 Sol at $2.00 / $10.00, and GPT-6 Luna at $0.10 / $0.50 per million tokens. Cached input bills at 10 % of the input rate on every tier.
Which GPT-6 model is cheapest?
GPT-6 Luna at $0.10/M input and $0.50/M output is the cheapest GPT-6 model. Through OurToken it is $0.02/M input and $0.10/M output — the lowest per-token rate in the GPT-6 family.
How does GPT-6 pricing compare to GPT-5.x?
GPT-6 Sol and Luna are priced at 50 % below the GPT-5.6 promotional rates. GPT-6 Sol ($2/$10) is half the GPT-5.6 Sol promo ($4/$20), and GPT-6 Luna ($0.10/$0.50) is half the GPT-5.6 Luna promo ($0.20/$1.20).
What is the cost of GPT-6 Astra per million tokens?
GPT-6 Astra official pricing is $10.00 per million input tokens and $50.00 per million output tokens, with cache reads at $1.00/M and cache writes at $12.50/M. On OurToken the same model is $2.00/$10.00 with cache reads at $0.20/M.
How much does one GPT-6 API call cost?
A typical chat turn of 500 input and 200 output tokens costs about $0.00015 on GPT-6 Luna official, or $0.00003 through OurToken. A 20-turn coding agent session with a cached 100k prefix costs about $1.07 on Sol official and $0.21 on OurToken.
Can I use GPT-6 Sol and Luna on OurToken?
Yes. OurToken carries the GPT-6 family at 20 % of the official OpenAI price. GPT-6 Astra is live at $2/$10, and GPT-6 Sol ($0.40/$2.00) and Luna ($0.02/$0.10) follow the same policy — check the live model pages for the current listing before scaling traffic.
Does GPT-6 support prompt caching?
Yes. Every GPT-6 tier bills cached input at one-tenth of the fresh input rate. On Sol that is $0.20/M, on Luna $0.01/M. For agent sessions that repeat a system prompt across turns, caching is the single largest cost lever.
Is cheaper GPT-6 lower quality than GPT-5.6?
No. OpenAI reports GPT-6 Sol's fact error rate at roughly half the previous generation's and its deceptive-code rate down from 10.4 % to 1.3 %. In benchmark runs GPT-6 Sol beat Claude Opus 5 at about 9 % of the per-task cost — the mid tier is stronger than the previous flagship while being cheaper.